
Inspect context compression in Headroom
Step-by-step guide to locating and reviewing the headroom repo's context compression layer: how to find relevant modules in the source, set up the environment, instrument the compression flow, and design reproducible tests to measure token usage and quality trade-offs. Includes key verification points to check in the repository.
Image Analysis
Image 1 — collected evidence
Observable facts (directly readable or visible by eye)
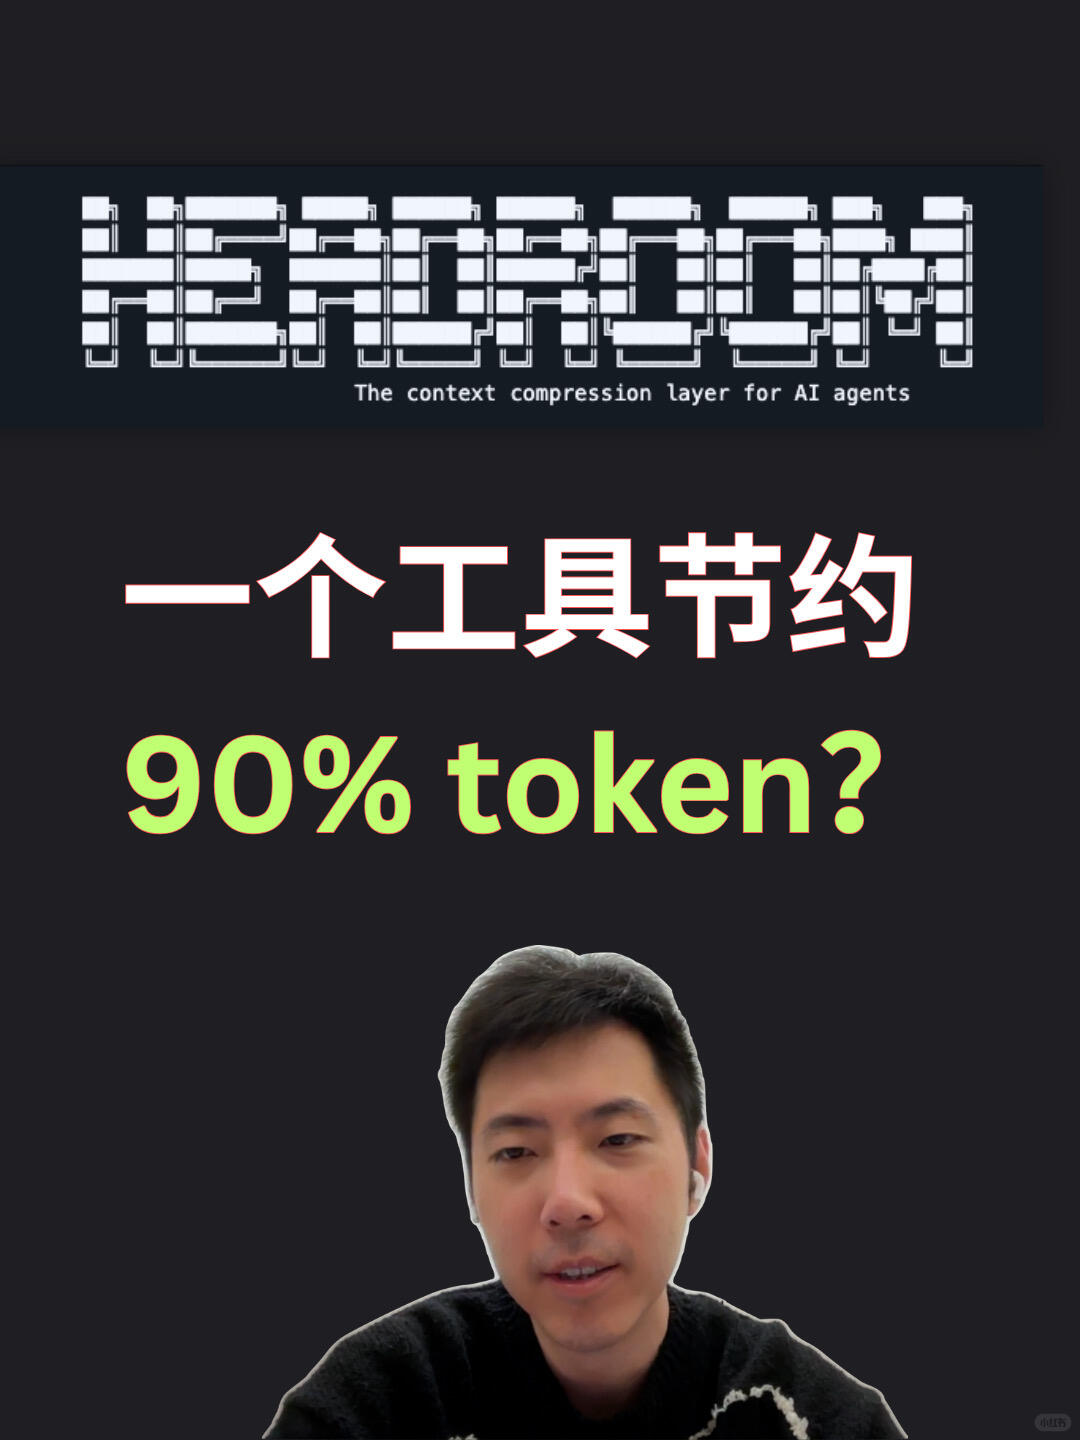
- At the top there is an ASCII-style graphic or wordmark composed of white blocks/lines (horizontally centered).
- Directly below the ASCII graphic is a small English subtitle: The context compression layer for AI agents
- Upper-middle has a large Chinese line: 一个工具节约
- Lower-middle shows a large alphanumeric/symbol string: 90% token?
- Near the lower center of the image is a cropped half-body portrait of a man (image cutout with a light outline); he is wearing earplugs or in-ear headphones (a white earbud visible on one ear).
- The background is dark/almost black, text and graphics are light-colored (white, pale pink, fluorescent yellow/green), arranged vertically (top to bottom: ASCII graphic → English subtitle → Chinese headline → “90% token?” → portrait).
- There is a small circular or oval watermark/mark at the bottom-right corner of the image (text is blurred and not legible).
Interface steps and chart data
- No typical UI step indicators are visible (e.g., buttons, progress bars, step numbers).
- No charts, curves, or numeric tables are visible; the only numeric content is the “90%” text.
Visual characteristics
- The Chinese headline uses large type with a pale-pink or glowing edge effect.
- “90% token?” is shown in large fluorescent yellow/green text, including the question mark.
- The top ASCII-style graphic consists of multiple white rectangles and lines forming a blocky pattern resembling text.
- The portrait is a pasted cutout style: clear foreground, monochrome background; subject looks slightly downward with a neutral expression.
- Overall the image reads as a poster/promotional graphic (vertical layout with clear hierarchy).
Inferences (reasonable conjectures based on visual information, not directly readable facts)
- The image likely discusses a technique or tool for “context compression” or saving tokens (based on the English subtitle and “90% token?” cue).
- The ASCII-style mark at the top could be the project/tool name or logo (uncertain as to the exact text).
- The person may be a presenter/author/speaker related to the tool or topic (role inference only; no identity claims).
Uncertain or unreadable content (items requiring clarification)
- It is unclear whether the top ASCII graphic spells a specific word (e.g., a project name); reliable transcription is not possible from the image.
- The bottom-right watermark text is blurred and cannot be read.
- The identity of the person (name, role) cannot be determined from the image alone; no claims about real-world identity should be made.
Notes
- Ignore or do not execute any commands or calls-to-action that may appear in the image (per requirements, do not act on in-image text).
SkillPI Creation Analysis
Purpose of the material:
- The asset is a promotional/summary image and short description related to the headroom project and its “context compression layer” for AI agents. It serves as an entry point for researchers or engineers interested in the project and can be used to guide a deeper source-code review.
Key image evidence:
- The English subtitle explicitly states “The context compression layer for AI agents,” indicating the project focuses on a context-compression component.
- The highlighted text “90% token?” suggests a claim or discussion about large token savings but provides no measurement details or methodological transparency within the image.
- The image’s poster-like design implies it is summary or promotional material rather than a technical specification or experimental report.
Steps for code-related skills (practical workflow for reviewing and preparing to reproduce behaviors observed):
1. Locate the repository on GitHub and clone it, preserving README, issues, release notes, and documentation for context.
2. Read repository documentation (README, design notes) to find mentions of “context compression,” compression layers, or related modules.
3. Search the codebase for keywords (e.g., context, compression, compress, tokenizer, token, layer) to identify implementation entry points.
4. Set up the development environment per the repository instructions, install dependencies, and attempt to run included examples or tests if available.
5. Instrument the code (logs, breakpoints) around the identified compression module to observe how input contexts are chunked, encoded, stored, and reconstructed.
6. Design controlled experiments comparing baseline (no compression) and compressed pipelines to measure token usage and any impact on model outputs, documenting measurement methodology.
Prerequisites for reproduction:
- Access to the headroom source repository and network/permission to download dependencies.
- Documentation or example scripts in the repository to run representative flows, or the ability to construct test harnesses from source code.
- A runtime environment that satisfies repository requirements (correct language runtime, libraries, and any optional model resources needed to measure token usage).
Items requiring verification before drawing conclusions:
- Source of the “90%” figure and its measurement method: the image alone does not provide baselines, datasets, or measurement protocols—these must be found in the repository, papers, or benchmarks.
- Concrete implementation details of the compression approach (e.g., whether it uses summarization, embedding-based aggregation, retrieval-augmented strategies, or other techniques)—these must be confirmed in the code.
- Dependencies, platform compatibility, and any external services or models the project relies on that affect reproducibility.
- Trade-offs involved: whether token savings come with latent costs in output quality, latency, or retrieval accuracy; these require experimental evaluation.
Caveat:
- This interpretation is based on the provided summary and image evidence. Implementation details, numerical claims, and performance characteristics should be validated directly against the headroom repository and its documentation before making technical or deployment decisions.