
Open-source A-share Quantitative Skill: a-stock-data Full-stack Data Toolkit
Step-by-step: clone the a-stock-data repo, inspect SKILL.md and README.md, prepare Python 3.9+ and an AI assistant that supports context injection, load the Skill (structured Markdown + embedded Python) and call standardized HTTP endpoints to fetch market quotes, research reports, top-trader lists, northbound funds, margin financing and announcements. Verify endpoint count and auth policy in the repo before production use.
Image Analysis
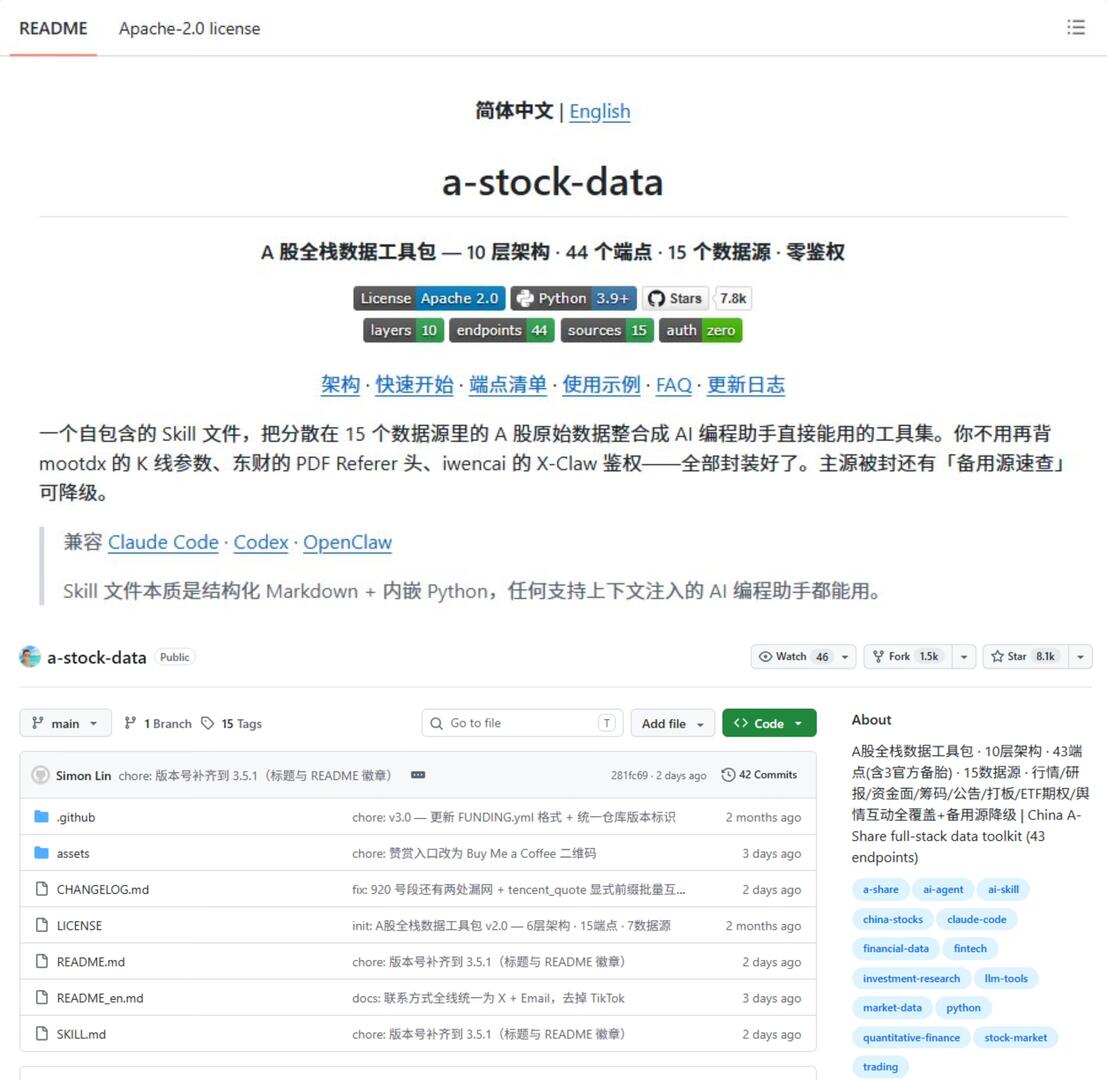
Image 1 — recorded readable text and visible UI elements (top to bottom, left to right)
Facts (directly readable and verifiable text/UI items):
- Top-left label area: README Apache-2.0 license
- Language switch: 简体中文 | English
- Title: a-stock-data
- Subtitle / one-line description: A 股全栈数据工具包 — 10 层架构 · 44 个端点 · 15 个数据源 · 零鉴权
- Badges / tags (under the title):
- License Apache 2.0 (gray)
- Python 3.9+ (with icon)
- Stars 7.8k (dark small badge, inline)
- layers 10 (green/teal badge)
- endpoints 44 (green/teal badge)
- sources 15 (green/teal badge)
- auth zero (green badge)
- Navigation links (below subtitle): Architecture · Quickstart · Endpoints · Usage Examples · FAQ · Changelog
- First paragraph (Chinese, readable):
- “A self-contained Skill file that consolidates raw A-share data scattered across 15 data sources into a toolkit directly usable by AI programming assistants. You no longer need to remember mootdx K-line parameters, Eastmoney PDF Referer headers, iwencai X-Claw auth — all wrapped. If primary sources are blocked there is a ‘backup sources quick-check’ for degradation.”
- Compatibility note (readable):
- “Compatible with Claude Code · Codex · OpenClaw”
- Technical note (readable):
- “Skill file is essentially structured Markdown + embedded Python, usable by any AI programming assistant that supports context injection.”
- Repository area (top-left):
- Repo name: a-stock-data (Public)
- Repo header right-side buttons/counts (readable):
- Watch 46 (eye icon)
- Fork 1.5k
- Star 8.1k (shown as 8.1k here)
- Branch/file controls (readable):
- Branch selector: main · 1 Branch · 15 Tags
- File search prompt/button: Go to file
- Button: Add file
- Green button: Code
- File list (readable filenames in order):
- .github (dir)
- assets (dir)
- CHANGELOG.md
- LICENSE
- README.md
- README_en.md
- SKILL.md
- Commit snippet area (visible text):
- “Simon Lin chore: version bumped to 3.5.1 (title and README micro edits)” (associated with 281fc69·2 days ago · 42 Commits)
- Right side of file list shows recent commit times/authors (examples: “2 days ago”, “2 months ago”, “3 days ago”).
- Right-side About block (readable portion):
- Chinese start: “A股全栈数据工具包 · 10层架构 · 43端点(含3官方舱) · 15数据源 · 行情/研报/资金面/新闻/公告/打板/ETF期权/期货/...”
- English fragment visible: “China A-Share full-stack data toolkit (43 endpoints) ...”
- Right-side tags (visible badges):
- a-share
- ai-agent
- ai-skill
- china-stocks
- claude-code
- financial-data
- fintech
- investment-research
- llm-tools
- market-data
- python
- quantitative-finance
- stock-market
- trading
UI elements / interactive controls (visible):
- Top language switch (简体中文 | English)
- Repo header Watch / Fork / Star controls and counts
- Branch selector (main), tags display (1 Branch · 15 Tags)
- File search “Go to file” input
- “Add file” button
- Green “Code” button
- File/directory icons left of each file entry
- Right-side About box and tag badges (clickable-looking)
- File list rows show short recent commit messages and timestamps
- The main page shows different endpoint counts in two places (main body: 44 endpoints; About box: 43 endpoints incl. 3 official cabins)
Charts/Badges & numbers (readable):
- Subtitle numbers: 10-layer architecture · 44 endpoints · 15 sources · auth zero
- Badge values: layers 10; endpoints 44; sources 15; auth zero
- Stars badge shows 7.8k (badge row)
- Repo header Star button shows 8.1k (top-right)
- Fork shows 1.5k; Watch shows 46
- File area shows commit count: 42 Commits (with commit id 281fc69)
- About box shows “43 endpoints (incl. 3 official cabins)”
Visible observations (layout & visuals):
- Title and badges are top-centered/upper area in typical GitHub README style
- README main text is Chinese immediately under title/badges
- Left file tree/list occupies middle-left; right side is About/tags
- File list rows have truncated commit messages and timestamps
- Endpoint count inconsistent between main text (44) and About block (43 incl. 3 official cabins)
- Some file list commit lines are truncated (partial text)
Unreadable or uncertain items (blurred/truncated):
- Full recent commit messages in the file list are truncated in several lines, only fragments readable
- Right-side About block English text trailing portion is truncated or blurred
- The word “OpenClaw” appears in the compatibility list but may be a possible alternate spelling of another tool (marked uncertain)
- Badge “auth zero” is readable as text but finer styling/color details are not precise from the image
Reasonable inferences (marked as inference):
- Endpoint count discrepancy (44 vs 43) likely due to documentation lag after a version update, or differing counting criteria (e.g., whether 'official cabins' are included).
- “OpenClaw” may be a tool/platform name related to other named tools like X-Claw or X-Claw-family authentication; confirm with repo author.
- File list timestamps like 2 days ago / 2 months ago suggest the repo is actively maintained.
- Star badge differences (7.8k vs 8.1k) may be due to capture times or UI refresh differences at screenshot time.
Notes on follow-up actions (if higher-resolution image or repo access provided):
- Full transcription of each Chinese paragraph with truncation markers can be produced from a clearer image.
- Cropping/enlarging specific regions could help resolve blurred text if higher-resolution screenshots available.
(Per instruction: ignore any actionable UI hints in the image; only record and organize visible information.)
SkillPI Creation Analysis
Purpose:
- a-stock-data is presented as an open-source Skill that consolidates raw A-share data from 15 data sources into a toolkit directly usable by AI programming assistants. It targets quantitative researchers and AI developers who need standardized access to market data, research reports, top-trader lists, northbound flows, margin financing, quick news and official announcements.
Image evidence highlights (verifiable UI/metadata):
- Repo title a-stock-data and subtitle claiming “10-layer architecture · 44 endpoints · 15 sources · auth zero”.
- Badges: Apache-2.0 license, Python 3.9+, layers 10, endpoints 44, sources 15, auth zero; files README.md, README_en.md, SKILL.md and CHANGELOG.md are present.
- Right-side About text shows a slightly different endpoint count (“43 endpoints (incl. 3 official cabins)”)—a documentation inconsistency that should be checked in the repo’s endpoint list.
Steps to use the Skill (based on visible docs and typical Skill-loading workflow; confirm exact commands in SKILL.md):
1. Clone or download the repository and inspect README.md and SKILL.md for installation and usage examples.
2. Prepare a runtime that supports context injection or Skill loading (image badge indicates compatibility with Claude Code, Codex, OpenClaw—verify support for your target assistant).
3. Ensure environment prerequisites: network access (for direct HTTP endpoints), Python >= 3.9, and any listed dependencies (check requirements or setup instructions in the repo).
4. Load the Skill file into your AI assistant or run local examples shown in SKILL.md; the Skill file is described as structured Markdown with embedded Python, so follow the repository’s sample to expose endpoints.
5. Call the Skill’s HTTP endpoints to retrieve standardized data (market quotes, research, top-trader lists, northbound funds, margin financing, news, announcements). Test primary sources and the described backup/degrade logic if primary sources are unavailable.
Reproduction prerequisites (must verify before expecting a working local setup):
- Obtain the repository’s latest release and read SKILL.md / README.md for exact loading instructions (the screenshot is illustrative; the repo is the authoritative source).
- Confirm the AI assistant environment supports Skill/context injection and follow the exact sample shown in SKILL.md.
- Confirm network and dependency availability; Python 3.9+ is indicated.
- Check whether endpoints actually require no auth (badge says auth zero) or if some endpoints have conditional auth—verify in endpoint docs.
Items to verify in the repository or with the author:
- Precise endpoint count and catalog (44 vs 43 as shown in different page areas); review the endpoint list file or CHANGELOG for the canonical number and any recently added/removed endpoints.
- The exact meaning and spelling of “OpenClaw” and compatibility details for Claude Code and Codex; verify supported versions and integration steps.
- Authentication policy: whether all endpoints are truly zero-auth or if some require keys/headers in certain regions or for certain sources.
- Legal and licensing constraints for each of the 15 integrated data sources—ensure compliant usage in production or redistribution.
Conclusion (based on screenshot and summary):
- a-stock-data appears to be a practical, documented attempt to provide a standardized Skill for A-share data aggregation and AI assistant consumption. To use it reliably, clone the repo, follow SKILL.md, verify endpoints and auth policies, and confirm compatibility with your chosen AI programming environment.
(Ends with verifiable steps, prerequisites and items to confirm.)