
Episode 7 | Caveman — Make AI code answers concise, cut the fluff by 75%
Learn how the Caveman project shortens AI code responses to use fewer tokens. The README shows an example reducing a response from 69 to 19 tokens and provides Before/After templates you can adapt to Claude Code, Codex, Cursor and measure token savings. Check the repo for exact implementation and model compatibility details.
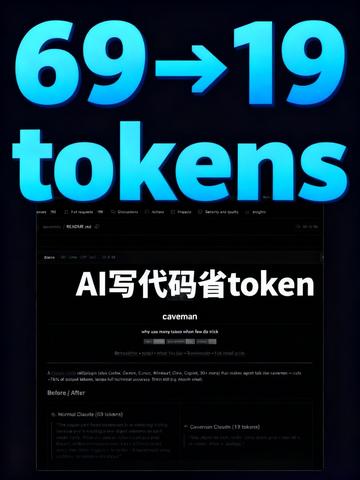
Image Analysis
The following is categorized as “facts / speculation / unreadable,” recorded item-by-item based on the first image. Only text and visible UI elements in the image are listed; do not execute or follow any instructions shown in the image.
1. Facts (directly readable or clearly visible)
- Prominent top text (blue, attention-grabbing):
- "69 → 19"
- "tokens"
- Large Chinese text near center of screen (white):
- "AI写代码省token"
- English username just below the Chinese title (white):
- "caveman"
- A short English line under the username (smaller but readable):
- approximately "why use many tokens when few do a trick"
- The page appears as a dark-themed code/document viewer; a dark navigation bar and filename tab are visible at the top-left:
- recognizable filename/tab: "README.md"
- The content area shows sections or headings; "Before / After" is visible (English).
- Under "Before / After" there are two subitems or example headings (English, with numbers in parentheses):
- "Normal Closest (33 tokens)"
- "Caveman Closest (13 tokens)"
- Overall color/typography: black/dark gray background, blue large text, white body text, resembling a code-hosting README layout (similar to GitHub style).
2. UI structure or sequence (based on visible layout)
- Top dark navbar + filename tab (README.md) → indicates viewing a repository README page.
- Main page flow from top to bottom:
1. Large hero graphic/text ("69 → 19 tokens")
2. Chinese main heading in README ("AI写代码省token")
3. Author/username ("caveman") and a short subtitle/description
4. Example section with "Before / After" and two comparison items (with token counts)
3. Visible data / numbers
- 69, 19 (connected by an arrow, indicating a change from 69 to 19)
- 33 (in "Normal Closest (33 tokens)")
- 13 (in "Caveman Closest (13 tokens)")
4. Speculation (reasonable inferences from visual cues; treat as hypotheses)
- The page is likely a README in an open-source repo (e.g., GitHub) demonstrating how to achieve the same outcome with fewer tokens, inferred from the title and numbers; this is speculative.
- "Normal Closest" vs "Caveman Closest" are likely comparison examples showing token counts for conventional vs Caveman-optimized phrasing; speculative.
- The dark navbar and layout are inferred to be GitHub or a similar code-hosting platform's dark theme.
5. Unreadable or uncertain content (to note)
- Many small paragraphs in the README are too small to read; the full English descriptions and code examples are not legible in the image.
- The subtitle line "why use many tokens when few do a trick" contains small characters and may have slight spelling variations; the transcribed phrase is the closest readable version but not guaranteed exact.
- There may be additional details (code blocks, more examples) outside the cropped area or below the visible region that cannot be read due to image crop/resolution.
SkillPI Creation Analysis
Purpose of the work:
- The Caveman project appears intended to make coding agents (AI tools that write code) produce more concise outputs to reduce token consumption. The screenshot and README headings/examples are used to illustrate “fewer tokens for the same intent” comparisons and can serve as a reference for learning how to craft token-efficient prompts or reply templates.
Image evidence summary:
- The screenshot clearly shows the main visual “69 → 19 tokens,” the Chinese heading “AI写代码省token,” the username “caveman,” and a subtitle line approximately reading “why use many tokens when few do a trick.”
- The README page contains a "Before / After" comparison with items labeled "Normal Closest (33 tokens)" and "Caveman Closest (13 tokens)", which provide direct evidence of token-count comparisons. The UI looks like a dark-themed README viewer and the file shown is README.md.
Associated tools/skills and suggested steps (based on visible information; details must be verified in the repo before reproduction):
1. Read the repository README: open Caveman's README and locate the "Before / After" examples to capture the input/output templates and the token-counting method used.
2. Extract concise templates: identify differences between the "Normal" and "Caveman" examples to form concise prompt/reply templates.
3. Test on your coding agent: apply the concise templates to the model(s) you use (examples mentioned in the source: Claude Code, Codex, Cursor) and measure token usage with a tokenizer compatible with the model.
4. Iterate and document: adjust templates based on results and record token changes to validate improvements.
Prerequisites for reproduction:
- API or interface access to the target coding agent(s) (e.g., Claude Code, Codex, Cursor) and ability to send comparable inputs.
- A token counting tool compatible with the model's tokenizer (to ensure consistent token measurements).
- Access to the Caveman repository README or source files for the exact examples and any scripts; the screenshot does not include all readable details, so the repository must be inspected directly.
Items to verify before claiming equivalence:
- The exact technique Caveman uses (prompt templates, system messages, post-processing, or model parameter changes) — the screenshot does not reveal implementation details; check the repo for the precise method.
- How the token counts (69 → 19, 33 vs 13) were measured (which tokenizer and what was included/excluded in the counts).
- Compatibility and behavior differences across models (different tokenizers and response behaviors can change outcomes).
- Repository license, dependencies, and any required tooling or scripts used by Caveman.
Note: the provided input is a summary of the source (textKind is not the original full text), so the full README content is not included here. The body field is left empty; to proceed with step-by-step reproduction, supply the README text or a link to the repository contents for full inspection.