
Headroom source code analysis
Learn step-by-step how to get and audit the Headroom repo: locate the "context compression layer", read its implementation, run examples, design repeatable benchmarks, and use a tokenizer to measure token consumption with and without the compression. The guide lists reproducibility prerequisites and items to verify so you can test the image's 90% claim independently.
Image Analysis
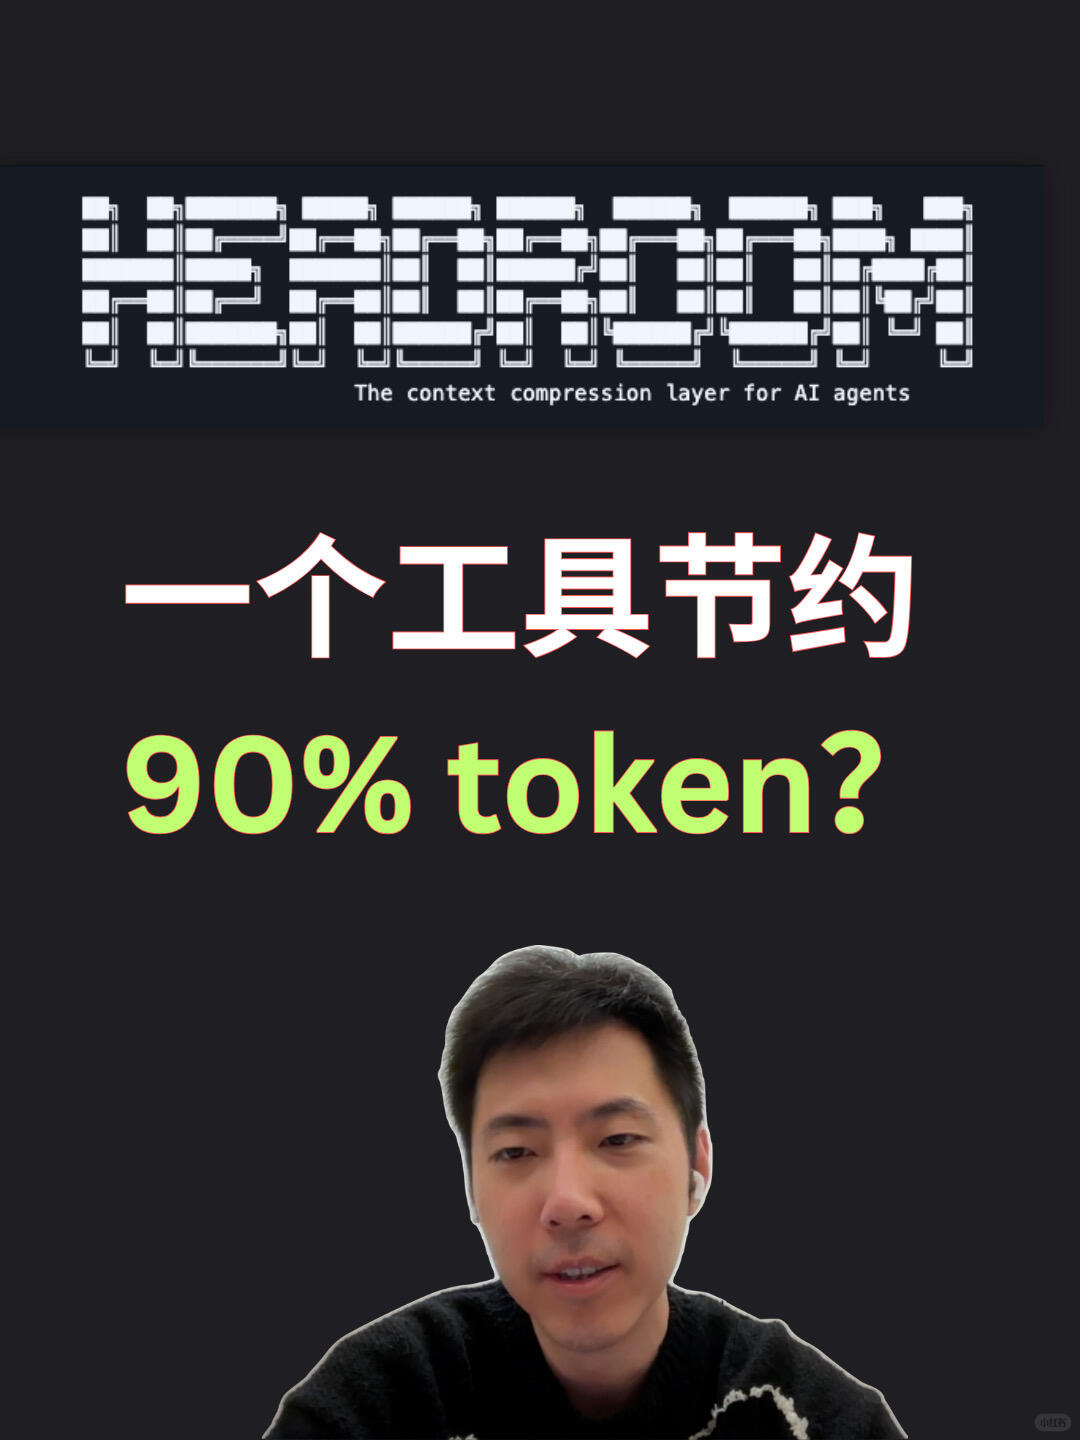
Image Evidence (Image 1) —整理
1. Facts (only directly readable or objectively visible content)
- Readable text (line/block):
- Under a top ASCII-style graphic, small English text: The context compression layer for AI agents
- Large Chinese central line: 一个工具节约 (a tool saves)
- Prominent midline (mixed English/Chinese, green): 90% token?
- Layout and UI elements:
- Background is dark (near black or dark gray).
- Top contains an ASCII-style graphic or logo in white, placed near the top center.
- Center shows a large Chinese headline; below it a large green “90% token?” text.
- Bottom-center shows a cropped upper-body photo (real person or screenshot) positioned against the dark background.
- A small circular or oval watermark/icon appears near the bottom-right edge (unreadable).
- Visible person and clothing (objective description, no identity inference):
- An adult photographed frontally or slightly sideways.
- The person wears an earbud or earphone (white earbud visible on the right ear).
- Wearing a dark top (black or dark gray) with some light-colored patterns or lines near collar/chest.
- Face is clearly photographed; skin tone and facial features are visible (no identity claims).
- Colors and style:
- The Chinese headline has a white outline (inner area possibly pale pink or light color), bold font.
- “90% token?” is light green / neon green and very prominent.
- Overall design is a minimalist dark poster.
2. Speculation (marked as speculation, not fact)
- The top ASCII graphic likely represents a project logo or stylized name; the small English text may be a subtitle or description (“The context compression layer for AI agents”).
- The Chinese headline together with “90% token?” likely implies the tool claims to save 90% of tokens (presented as a question or claim).
- The bottom photo could be a presenter’s screenshot, speaker photo, or promotional image (earbud suggests a recording or talk screenshot).
- The small watermark may indicate the hosting platform or a production tool, but it is too small to identify.
3. Uncertain / unreadable items (need higher resolution or extra info)
- The exact letters/words inside the top ASCII graphic are not legible; cannot confirm precise logo text.
- The bottom-right small watermark’s symbol or text is unreadable (too small / blurred).
- Any small print (author, timestamp, copyright) is not legible at current resolution.
- The Chinese phrase visible as “一个工具节约” may be truncated or cropped and not necessarily the full headline.
Notes
- Any possible “action instructions” in the image were ignored per requirements; facts and speculations are separated.
- No identity recognition performed on the pictured person; only objective appearance details recorded.
SkillPI Creation Analysis
Intended use of the project
- The image and brief tagline indicate Headroom positions itself as a “context compression layer for AI agents,” suggesting its purpose is to reduce the tokens required to represent or transmit long context windows when interacting with large models.
Image evidence summary
- The poster-style image displays a subtitle that reads “The context compression layer for AI agents” and a prominent “90% token?” claim. This is promotional or summary-level evidence only and does not provide implementation details or measurement methodology.
Associated skills and reproducible analysis steps (no specific Skills provided in the source; below are general, practical steps to audit the repository and measure token usage)
1) Obtain the code: locate and clone the official Headroom repository; inspect README, docs, and examples.
2) Identify core modules: search the codebase for terms like "compress", "context", "token", "encoder", "summarize", "embedding", or "buffer" to find candidate implementations of a compression layer.
3) Read implementations and docs: trace data flow, note interfaces between the compression layer and model I/O, and record external dependencies (vector stores, encoders, summarizers).
4) Execute examples/tests: run provided examples or create minimal demo scripts to exercise the compression pipeline.
5) Measure tokens: use a tokenizer appropriate to the target model (tokenizer libraries/tools) to count tokens for identical prompts with and without the compression layer enabled; ensure identical prompts and environment.
6) Benchmark and evaluate: run repeated trials with a fixed input set to compute average token counts, latency, and qualitative differences in output fidelity.
7) Analyze strategy: from reading the code, determine whether compression is done via summarization, chunking + retrieval, embeddings + indexing, custom encoders, or another approach, and reason about tradeoffs.
Prerequisites for reproduction
- Access to the official Headroom repository and a clear version or tag to test;
- Environment and dependencies required by Headroom (language runtime, libraries, any external services);
- A tokenizer or token-counting tool compatible with the target model to measure token consumption;
- A set of representative prompts/contexts and evaluation criteria for output fidelity.
Open items to verify (not proven by the provided image/summary)
- Whether the “90% token” figure is an empirical result, a best-case example, a dataset-specific outcome, or a marketing claim;
- The exact algorithmic technique used by Headroom’s compression layer (the image and one-line summary do not reveal the implementation);
- Any reliance on external proprietary services, pre-trained modules, or dataset-specific optimizations that could affect reproducibility.
Notes and caution
- The image and short summary provide promotional claims, not reproducible measurements; independent code review and controlled benchmarks are required to validate any percentage claims.
- If you share the repository link or allow creation of concrete benchmark scripts, I can draft a reproducible benchmarking plan and token-counting script using standard tokenizer libraries (the plan will rely only on public tools and explicit steps).